Jev: What It Is, What You Can Use It For, and Where It Fits
People are still figuring out ChatGPT and Claude. Now another AI name is entering developer conversations: Jev.
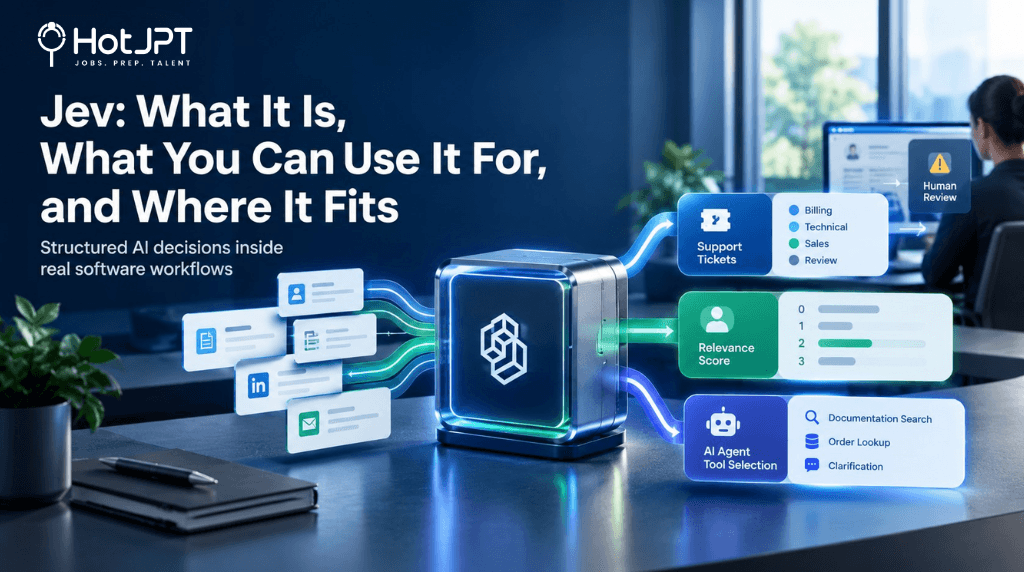
But Jev is not simply another chatbot. Its core idea is narrower: give the system context and a defined decision to make, then return a structured result that software can use.
That makes Jev potentially useful for classification, scoring, routing, and yes/no decisions — especially inside AI agents and automated workflows.
The important question is not whether Jev replaces general-purpose AI.
It is: Where does a specialized decision model actually make sense?
Jev is a System One model from TypeSafe designed for structured decisions.
Instead of generating paragraphs like a traditional LLM, Jev can return choices, scores, or yes/no probabilities based on options and criteria you define.
The practical opportunity is to use it for repeated decisions inside software, while keeping normal code and humans responsible for permissions, execution, and review.
Define the possible answers. Jev judges which ones fit.
What is Jev?
An LLM such as ChatGPT or Claude generates text token by token. Jev takes a different approach.
You provide context and a clearly defined question. It returns a structured decision that your software can consume. It is not designed to write your email, create a LinkedIn post, or explain an answer in long-form prose.
TypeSafe describes Jev as a System One model. Its founder, Diogo Almeida, previously worked at OpenAI on instruction-following methods. Jev launched on September 15, 2026.
TypeSafe also describes RLCD, or Reinforcement Learning for Calibrated Decisions, as its training approach. The goal is for probabilities attached to decisions to better reflect how frequently those decisions are correct.
Jev's three basic decision formats
| Format | What it does | Example |
|---|---|---|
| Choice | Selects one option | Billing, technical, sales, or review |
| Score | Rates something against defined levels | Relevance from 0–3 |
| Noul | Answers a yes/no question with a probability | Does the customer want to cancel? |
The important distinction is that confidence is not the same as probability of correctness. For Choice and Score, confidence summarizes how concentrated the returned probabilities are. It should not be interpreted as a guarantee that a decision is accurate.
1. Find people worth messaging on LinkedIn
One practical use case is turning a large LinkedIn connections export into a shortlist.
Imagine you have thousands of connections but want to identify people relevant to a specific introduction, client opportunity, or collaboration.
A possible workflow is:
- Export your LinkedIn connections.
- Keep the original names and URLs locally.
- Give Jev only the professional information required for the decision.
- Score each connection against a defined relevance rubric.
- Send the shortlist to a writing model for message drafting.
- Review the final list yourself.
The source example uses four relevance levels:
- 0: No apparent relevance
- 1: Indirect relevance
- 2: Clear role or company relevance
- 3: Strong direct relevance
A separate yes/no question can check whether the supplied information is sufficient to judge relevance. Records with insufficient information can then go to human review instead of automatically becoming poor matches.
Copy-paste prompt
Build a local LinkedIn outreach shortlisting tool using Jev.

My goal: [specific introduction, client, or collaboration].
Target roles and companies: [list].

Evaluate each record using a Score with four ordered levels:

0: No apparent relevance.
1: Indirect relevance.
2: Clear role or company relevance.
3: Strong direct relevance to the stated goal.

Ask a separate yes/no question:

Is the supplied professional information sufficient to judge relevance?

Route insufficient records to review.

Export record ID, score, probabilities,
confidence, and review status.

Don't invent relationship strength,
hiring plans, or response likelihood.

Start with 20 records before a full run.
One important limitation remains: a job title can suggest relevance, but it cannot establish someone's willingness to refer you, hiring plans, or purchasing budget.
2. Route support tickets to the right team
Support routing is another straightforward decision problem.
A ticket saying "I was charged twice" could go to billing.
"I can't sign in" could go to technical support.
An unclear request involving multiple teams could go to human review.
Jev can make the classification while your existing software handles the actual routing.
For example:
| Team | Criteria |
|---|---|
| Billing | Charges, invoices, refunds, subscriptions |
| Technical | Login failures, bugs, broken integrations |
| Sales | Pre-purchase pricing or product questions |
| Review | Ambiguous, multi-team, or unsupported requests |
The source recommends first testing the system against tickets your team has already labeled before allowing automatic routing.
That distinction matters.
Jev makes the decision. Your software still executes the action.
3. Help an AI agent choose its next tool
AI agents often have several possible actions available.
For example, an agent might need to:
- Search product documentation
- Look up an order
- Ask the user for clarification
Jev can help select among those existing actions.
Your application still needs to execute the selected tool and enforce permissions.
A simple decision structure could look like this:
{
  "next_tool": {
    "type": "choice",
    "instructions": "Choose the next tool using the user request and available context. Select clarify when necessary details are missing.",
    "criteria": {
      "search_docs": "Find product instructions or policy",
      "lookup_order": "Read an order using an available order ID",
      "clarify": "Missing details or no suitable tool"
    }
  }
}
This is where Jev's role becomes clearer.
It is not necessarily the entire AI agent.
It can be one decision component inside the agent.
And access control should remain in code rather than relying on prompt instructions alone.
What the early evidence actually tells us
There is some early evidence beyond TypeSafe's own documentation.
A LangChain evaluation reported that Jev averaged 0.44 seconds per call and $0.00035 per call, matching human pass/fail labels on 500 repeated decisions.
But there is an important limitation.
Those 500 decisions came from five fixed weather-agent examples repeated 100 times each.
That makes the result relevant to that narrow evaluation. It does not establish performance across hundreds of unrelated real-world decision problems.
The same caution applies to claims around hallucination.
A constrained output format can prevent the model from inventing arbitrary paragraphs. It does not guarantee that the selected answer is correct.
TypeSafe's documentation identifies weaknesses involving arithmetic, distracting context, and adversarial inputs.
So the useful distinction is:
Structured output can reduce one class of failure. It does not eliminate incorrect decisions.
How much does Jev cost?
As of September 26, the source lists Jev at $0.042 per million input tokens, with free output.
For illustration, consider 5,000 records with 600 total input tokens per record.
That equals:
5,000 × 600 = 3,000,000 input tokens
At $0.042 per million:
3 × $0.042 = $0.126
So the illustrative Jev input charge would be $0.126.
That is an arithmetic example, not a measured bill. Retries, larger prompts, development costs, and other parts of the workflow can add cost.
Where Jev fits — and where it doesn't
The easiest way to think about Jev is as a specialist decision component.
| Task | Potential fit |
|---|---|
| Classification | Strong use case to test |
| Scoring | Strong use case to test |
| Yes/no judgments | Strong use case to test |
| Agent tool selection | Possible use case |
| Support routing | Possible use case |
| Writing long-form content | Not its core role |
| Drafting emails | Not its core role |
| Executing privileged actions | Should remain in application code |
| Guaranteeing correct decisions | Not supported |
This distinction prevents the common mistake of treating every new AI model as another general-purpose chatbot.
Jev's value proposition is narrower: make defined decisions that software can consume.
Save This: The Jev Workflow
Use this sequence when deciding whether a task is a good candidate:
1. DEFINE
What exact decision needs to be made?
2. CONSTRAIN
What are the possible answers?
3. RUBRIC
What makes one answer better than another?
4. TEST
Label around 20 real examples yourself.
5. REVIEW
Inspect mistakes, especially confident mistakes.
6. INTEGRATE
Let your application execute the selected action.
7. EXPAND
Only increase automation after the evaluation supports it.
The source recommends starting with one repeated decision, labeling 20 examples, testing Jev, and inspecting mistakes before expanding the trial.
How to Find Your Own Jev Use Case
If you're a developer, recruiter, operations professional, or AI builder, start with the decisions you make repeatedly.
Ask:
- What choices do I make dozens or hundreds of times?
- Can I clearly define the possible answers?
- Can I write a consistent rubric?
- Do I already have examples of good and bad decisions?
- What happens if the model gets one wrong?
- Should uncertain cases go to a human?
- Could ordinary code or a spreadsheet solve this more simply?
The best candidate is not necessarily the most complicated workflow.
It is often the small, repetitive decision where the inputs and acceptable outputs are easy to define.
The HotJPT Take
Jev is easier to understand when you stop asking "Is this the next ChatGPT?"
The more useful question is:
"Which decisions in my workflow are structured enough for a specialized model to handle?"
That could mean routing support tickets, scoring leads, selecting an agent tool, or filtering a large dataset.
The right starting point is not a massive production rollout.
It is one repeated decision, 20 labeled examples, and a careful look at the mistakes.
Don't automate the whole workflow first. Automate one decision, measure it, then earn the right to automate more.
Frequently Asked Questions
Is Jev another ChatGPT?
No. Jev is positioned as a specialized System One decision model rather than a general conversational model. Its documented formats focus on Choice, Score, and Noul decisions.
What can Jev be used for?
Jev can be used for structured decisions such as classification, scoring, routing, yes/no judgments, and selecting among predefined actions in AI-agent workflows.
Does Jev's confidence mean the answer is correct?
No. Confidence should not be interpreted as a guarantee of accuracy. TypeSafe distinguishes confidence from the probability that a decision is correct.
Can Jev automatically execute actions?
Jev can help select an action, but the surrounding application should execute the action and enforce permissions. For agent workflows, access controls should remain in code.
The HotJPT editorial team covers AI, US immigration, IT job market trends, and staffing intelligence for recruiters, bench sales marketers, and IT consultants.